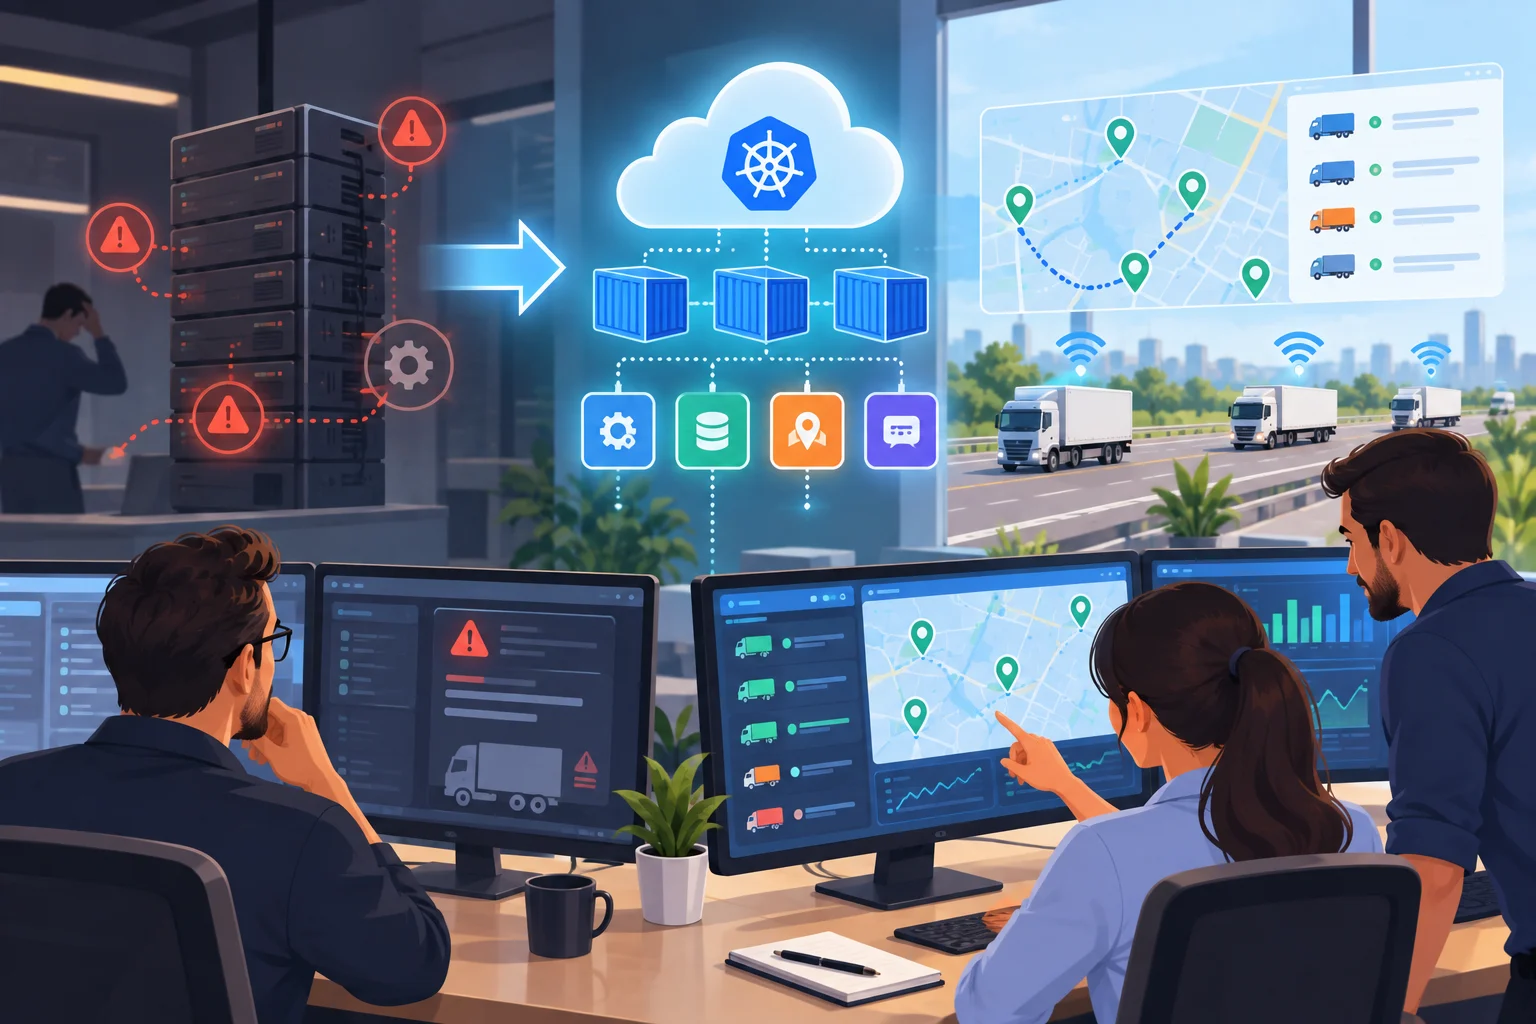
The fleet-tracking system had been built years earlier as one large application, and by the time we got involved, the cracks were hard to ignore:
The client didn’t want a full rewrite. The fleet-tracking logic itself worked fine — it was the architecture underneath that was holding them back.
Rather than rebuild from scratch, we took an incremental approach to breaking the monolith apart. First, we mapped out logical boundaries in the existing application — GPS tracking, driver notifications, route history, and reporting could each stand on their own as separate services. We containerized each one using Docker so they could be deployed, updated, and scaled independently.
Migration happened one service at a time, starting with reporting since it was the lowest-risk piece, and working up to GPS tracking last, once we’d confirmed the approach held up in production without issues.
The database ended up being the harder part of the project. The original system had a single shared database that every part of the application read and wrote to directly, so separating services meant untangling which service actually owned which data — without breaking historical reports that dispatch managers pulled from daily. A few edge cases around older trip records took extra work to sort out, since some of that data didn’t cleanly map to a single service.
We also set up per-service monitoring using Prometheus, with alerts routed to the team’s Slack, so if the notification service started failing, it would get flagged within minutes instead of someone noticing only after drivers started calling in.
Deployment time for routine updates dropped from several hours with scheduled downtime to under 15 minutes, with most releases now going out without any downtime at all. A failure in one service, like a delay in the notification module, no longer risked taking down GPS tracking or other features. The team could also scale GPS tracking on its own during peak dispatch hours instead of over-provisioning the entire application, which cut server costs during quieter periods. Overall, the dev team went from shipping updates every couple of weeks to almost twice that pace.
One thing that’s still a work in progress: the reporting service occasionally needs manual reconciliation against older historical data that hadn’t fully migrated over, since some legacy trip records predate the service split. The team is working through backfilling that data gradually rather than migrating it all at once.
Frontend: ReactJs
Backend: NodeJs
Mobile: Flutter
Database: MongoDB & Redis
Cloud/Hosting: AWS
Other Tools/Integrations: Flolive